DNS Tunneling Explained: Detection Signs and Practical Defenses

DNS Tunneling Explained: Detection Signs and Practical Defenses

DNS is essential to almost every online activity, so organizations commonly allow it through network boundaries. Attackers can abuse that trust by encoding command-and-control messages or stolen data inside DNS queries and responses. This technique is known as DNS tunneling.

A tunnel is difficult to identify from a single lookup because each message may still be a syntactically valid DNS request. Detection depends on combining DNS telemetry, endpoint context, traffic patterns, and a clear understanding of what is normal for the environment.

What is DNS tunneling?

DNS tunneling uses DNS as a carrier for data that the protocol was not intended to transport as an application channel. A compromised device encodes small pieces of information into query names or other fields. An attacker-controlled authoritative server receives and decodes those pieces, and its DNS responses may return commands or additional data.

The technique can support covert command and control, data exfiltration, or a restricted two-way connection. It does not require a vulnerability in DNS itself. Instead, it takes advantage of the fact that DNS traffic is widespread, often trusted, and sometimes logged less thoroughly than web or email traffic. The ClouDNS overview of DNS tunneling provides a complementary explanation of the attack and its indicators.

How a DNS tunnel works

  1. An attacker prepares a domain. The domain is delegated to an authoritative name server the attacker controls.
  2. A device is compromised. Malware or another unauthorized process gains the ability to make DNS requests.
  3. Data is encoded. Small chunks are placed in subdomain labels, for example as long strings that appear random.
  4. The query follows the normal DNS path. An approved recursive resolver may forward it toward the attacker’s authoritative server. The article What Is the Role of the Recursive DNS Server? explains this intermediary role.
  5. The attacker decodes the request. The authoritative server extracts the embedded data and can place an encoded reply in its answer.
  6. The exchange repeats. Many small transactions form a low-bandwidth channel that can blend into legitimate name resolution.

Implementations vary. Queries may use A, AAAA, CNAME, TXT, or other record types, and an attacker can trade speed for stealth. Knowing the purpose of common records, as described in DNS Record Types Every Beginner Should Know, helps analysts distinguish routine use from unexpected behavior.

Warning signs in queries and responses

No single indicator proves that a tunnel exists. Content delivery networks, email security systems, tracking platforms, and legitimate security tools can also generate unusual-looking names. Confidence rises when several signals occur together and endpoint activity supports the same conclusion.

Long or high-entropy labels

Encoded data often produces labels that are unusually long and contain a high proportion of seemingly random letters and digits. Compare label length, character distribution, and meaningful substrings with the baseline for the same domain and client population.

Many unique subdomains

A tunnel may create a new subdomain for every data fragment. A single device requesting hundreds or thousands of unique names below one parent domain is more suspicious than repeated access to a small, stable set of application hostnames.

Unusual volume or timing

Regular beaconing, bursts of queries from one endpoint, or continued DNS activity while the user is idle can indicate automation. Look at the number of requests per client and per parent domain, not only the network-wide total.

Unexpected record types and answer patterns

A sudden increase in TXT queries, oversized responses, repeated NXDOMAIN answers, very short TTL values, or an unusual ratio between query and response sizes can justify investigation. These patterns also have legitimate causes, so they should be correlated with application and host telemetry.

Bypassing approved resolvers

Endpoints that send DNS directly to public resolvers, use unapproved encrypted DNS services, or open port 53 to unfamiliar external systems may be avoiding organizational controls. A documented resolver policy makes these deviations easier to detect.

A practical detection workflow

Centralize DNS telemetry

Collect queries, response codes, record types, answer sizes, client identity, resolver identity, and timestamps from approved resolvers. Retain enough history to compare current behavior with a meaningful baseline while respecting privacy and retention requirements.

Build behavioral baselines

Measure normal query rates, common domains, typical label lengths, frequently used record types, and known automated services. Baselines should distinguish servers, user workstations, development systems, and network appliances because their normal patterns differ.

Combine multiple signals

Useful analytics include label length, entropy, the number of unique subdomains, request frequency, response size, NXDOMAIN rate, and the concentration of traffic on one domain. Multi-signal rules reduce false positives compared with treating any long hostname as malicious.

Correlate with endpoint and network evidence

Identify the process that initiated suspicious queries. Check process ancestry, command lines, file changes, user activity, outbound connections, authentication events, and recent alerts. A domain may look strange while being legitimate; an unknown process repeatedly querying it is stronger evidence.

How to reduce the risk

Enforce approved DNS paths

Configure clients to use managed resolvers and block direct outbound DNS on UDP and TCP port 53 from ordinary endpoints. Restrict DNS over TLS on port 853 to approved services and define a policy for DNS over HTTPS so applications cannot silently bypass monitoring.

Filter and inspect at the resolver

Use threat intelligence, carefully reviewed response-policy zones, domain reputation, and anomaly detection at central resolvers. Rate limiting can slow some tunnels but should be tuned to avoid disrupting legitimate workloads. Test every blocking rule and provide a way to investigate false positives.

Limit what a compromised host can reach

Network segmentation, egress controls, least privilege, application allowlisting, timely patching, and endpoint detection reduce both the chance of compromise and the value of a tunnel. DNS monitoring is strongest when it is one layer in a broader security architecture.

Monitor encrypted DNS deliberately

Encryption protects legitimate DNS privacy but can reduce visibility for network sensors. Managed endpoints should use organization-approved encrypted resolvers, with policy and telemetry at the client or resolver. Blocking every encrypted DNS service without a supported alternative may create operational problems and encourage workarounds.

What DNSSEC does—and does not—do

DNSSEC lets a validating resolver verify the authenticity and integrity of signed DNS data. It does not determine whether a client is using legitimate hostnames for an illegitimate data channel, so DNSSEC does not prevent DNS tunneling. Likewise, encrypted transports such as DoH or DoT protect traffic in transit but do not guarantee that the queries themselves are benign.

DNS tunneling is also different from spoofing or cache poisoning. Spoofing attempts to make a resolver or client accept a false answer; tunneling creates a covert communication path through queries and responses. For that separate threat, see DNS Spoofing: How to Prevent It.

Incident response when a tunnel is suspected

  1. Preserve evidence. Save resolver logs, endpoint telemetry, relevant packet data, and alert timelines before short retention periods erase them.
  2. Contain the endpoint. Isolate the affected device while keeping evidence available for analysis.
  3. Block the infrastructure. Add confirmed malicious domains and destinations to resolver and egress controls, while considering shared infrastructure and false-positive risk.
  4. Identify the initiating process. Determine how it started, what privileges it held, and whether persistence or additional malware is present.
  5. Assess data exposure. Estimate what information may have crossed the tunnel and follow the organization’s notification and recovery procedures.
  6. Hunt for related activity. Search other clients for the same domain, query pattern, executable, credentials, or persistence mechanism.
  7. Recover and improve. Remove the root cause, rotate exposed secrets, validate the device, and tune detections using what the incident revealed.

Protocol limits that matter to detection

DNS names and messages have defined size and label constraints. Tunnel implementations must work within those limits, which is one reason encoded data often appears as repeated, segmented labels. The authoritative protocol reference is RFC 1035: Domain Names—Implementation and Specification. Analysts should use protocol-aware parsers instead of assuming that every unusual string is valid DNS.

Conclusion

DNS tunneling turns a necessary protocol into a covert channel, but it usually leaves behavioral clues. Centralized logging, baselines, multi-signal analytics, endpoint correlation, approved resolver enforcement, and controlled egress provide a practical defensive strategy. Treat suspicious DNS as an investigation lead rather than automatic proof, and combine network evidence with host context before taking disruptive action.
DNS SERVFAIL Explained: Causes and Step-by-Step Troubleshooting

DNS SERVFAIL Explained: Causes and Step-by-Step Troubleshooting

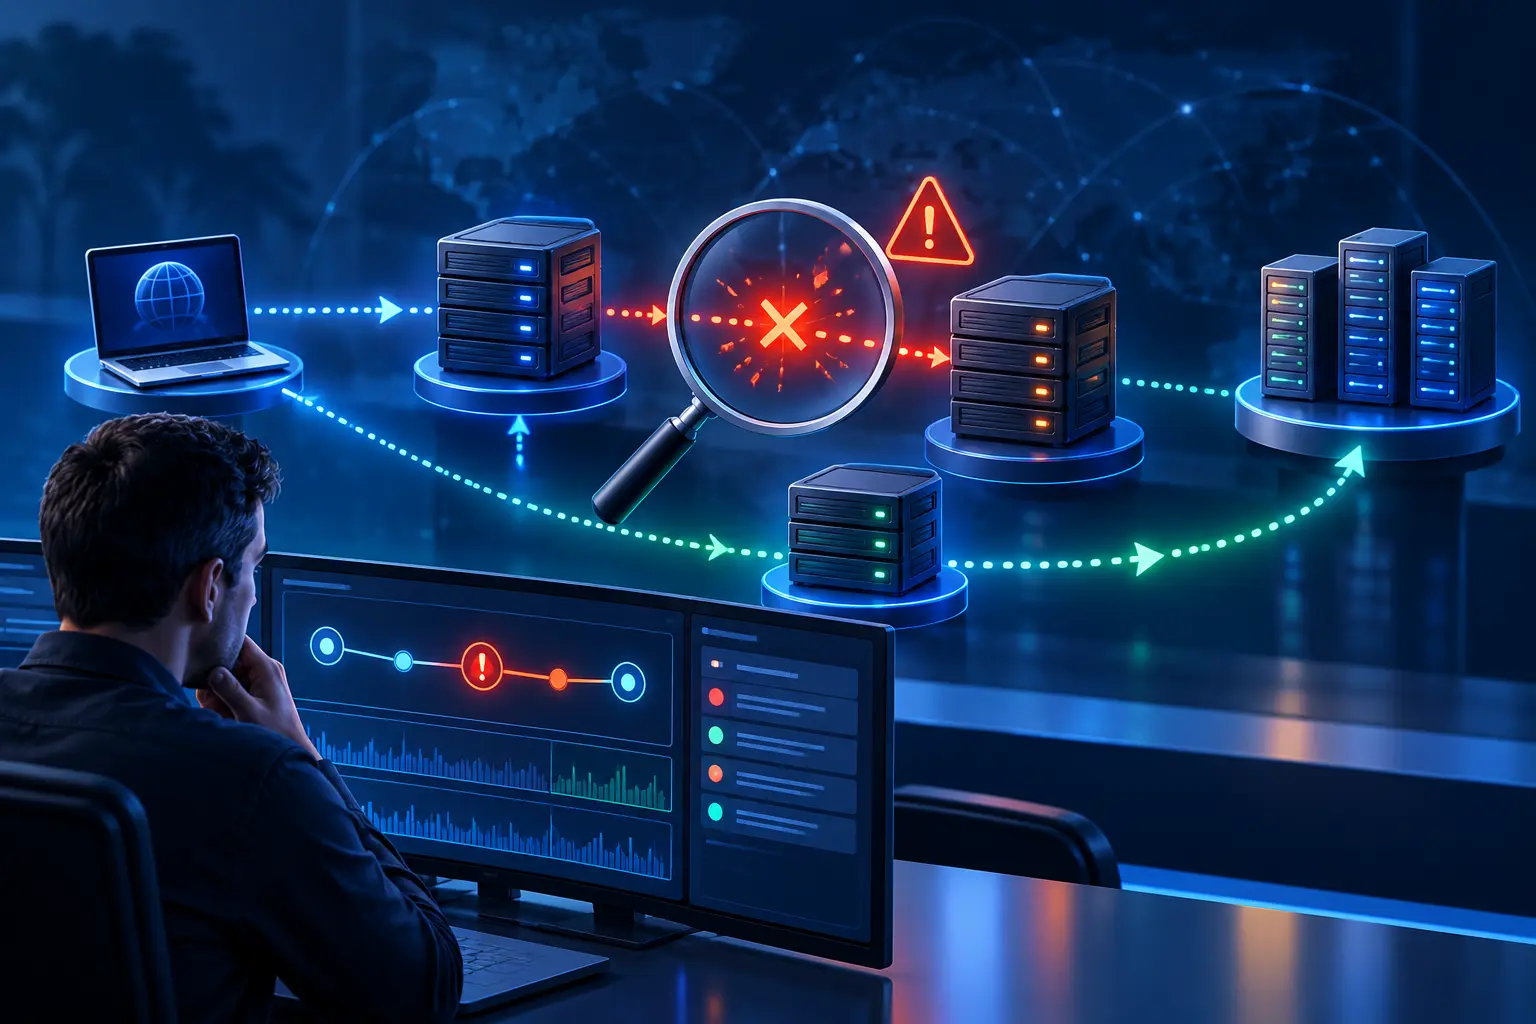
A DNS query that returns SERVFAIL tells you that the server could not complete the resolution process. The domain may exist and its records may be configured, but something prevented the responding resolver from producing a reliable answer. Because several different failures share this response code, the useful question is not simply “Is DNS down?” but “At which step did resolution fail?”

Effective troubleshooting compares resolvers, queries authoritative servers directly, checks delegation, reviews DNSSEC validation, and looks for timeouts or inconsistent data. This guide presents a repeatable process for narrowing the problem without changing records blindly.

What does DNS SERVFAIL mean?

SERVFAIL is DNS response code 2, meaning the name server encountered a failure while processing the request. It differs from NXDOMAIN, which says the queried name does not exist, and from NOERROR with an empty answer, which may mean the name exists but has no record of the requested type.

A recursive resolver can return SERVFAIL when it cannot reach an authoritative server, receives unusable responses, detects a broken delegation, fails DNSSEC validation, reaches a query limit, or encounters another internal error. The short response does not identify the cause by itself, so the next task is to collect evidence.

Start with a reproducible query

Use a command-line DNS tool so you can see the response code, flags, answering server, timing, and record sections. For example:

dig example.com A
dig example.com A @1.1.1.1
dig example.com A @8.8.8.8

The site’s existing Dig command guide explains the output and common query forms. Another beginner-friendly reference is this Dig command walkthrough. Both are useful before interpreting differences between recursive and authoritative answers.

Record the exact name, type, resolver, time, and result. A failure for an AAAA query does not prove that the A record fails, and a cached answer from one resolver does not prove that every resolver sees the same state.

Compare multiple recursive resolvers

Ask at least two independent recursive resolvers for the same name and type. If one returns a valid answer while another returns SERVFAIL, the zone may be healthy and the problem may involve cached state, DNSSEC validation, transport behavior, or a resolver-specific issue. If every resolver fails, focus on delegation and the authoritative service.

Also compare the failing network with a different connection. A local firewall, filtering product, VPN, or router can affect DNS traffic. Testing from another network helps separate a domain-wide fault from a client or access-network problem.

Trace the delegation path

The +trace option follows delegation from the root toward the target zone:

dig +trace example.com A

Look for the point where useful responses stop. Common delegation problems include nameservers listed at the parent that do not serve the child zone, missing glue for in-bailiwick nameservers, unreachable server addresses, and inconsistent NS sets between parent and child.

A delegation can appear correct in a control panel while the live parent zone contains older or different data. Query the parent-side information and each delegated nameserver rather than relying only on the provider interface.

Query authoritative servers directly

After identifying the delegated nameservers, resolve their addresses and query each one:

dig example.com A @ns1.example.net
dig example.com SOA @ns1.example.net
dig example.com NS @ns1.example.net

A healthy authoritative server should answer consistently and set the authoritative-answer flag for data in its zone. If one server times out or has an older SOA serial while the others respond correctly, investigate synchronization, firewall rules, routing, and service health on that server.

Test over both UDP and TCP when the symptoms suggest truncation or transport filtering:

dig example.com A @ns1.example.net
dig +tcp example.com A @ns1.example.net

DNS normally begins with UDP for many queries, but TCP is required in several situations and must not be blocked indiscriminately. Large responses, DNSSEC data, and retry behavior can expose a firewall that permits UDP while dropping TCP.

Check DNSSEC validation

A DNSSEC-validating resolver returns SERVFAIL when it cannot build a valid chain of trust or verify signed data. Typical causes include an incorrect DS record at the parent, expired signatures, missing signatures, a key rollover performed in the wrong order, or inconsistent signed responses across authoritative servers.

Compare a normal query with one that disables validation checking at the diagnostic client:

dig example.com A +dnssec
dig example.com A +dnssec +cdflag

If a validating lookup fails but the checking-disabled query returns data, investigate DNSSEC rather than treating the returned data as proof that the zone is healthy. Review the site’s guide on how to use DNSSEC securely for the purpose of signatures and the chain of trust.

Do not remove the parent DS record as an unplanned first response. A DNSSEC repair must coordinate the child-zone keys, signatures, and parent delegation. Improper changes can extend the outage or remove the intended protection.

Inspect the zone for structural problems

Authoritative data can be reachable yet still lead resolvers into failure. Check for:

  • CNAME loops: One alias ultimately points back to itself through one or more names.
  • Excessive alias chains: Long chains consume resolver work and introduce more failure points.
  • Broken dependencies: An NS, MX, or CNAME target depends on a name that cannot be resolved.
  • Inconsistent zone copies: Authoritative servers publish different records or SOA serials.
  • Invalid server configuration: The service loads an incomplete zone, rejects queries, or is not authoritative for the expected name.

Validate the zone file with the authoritative server software’s checking tools before loading it. After a change, query each authoritative server directly to confirm that the intended version is active everywhere.

Separate propagation from failure

DNS caches can temporarily preserve older positive or negative answers after a planned change. That behavior is often described as propagation, but an actual SERVFAIL usually indicates that a resolver could not complete or validate resolution, not merely that it retained an old value.

The article Understanding DNS propagation explains TTL-driven cache timing. Use TTL and cache history to interpret different answers, but continue investigating when resolvers consistently return a failure code.

Look for Extended DNS Error details

Some resolvers attach an Extended DNS Error option that provides a more specific reason, such as DNSSEC bogus data, no reachable authority, a network error, or a response considered stale. Recent versions of dig may display this information in the response.

Extended error text is diagnostic context rather than a replacement for the DNS response code, and support varies. The standardized codes and their intended use are defined in RFC 8914: Extended DNS Errors.

A practical SERVFAIL checklist

  1. Repeat the exact query and save the full output.
  2. Compare at least two independent recursive resolvers.
  3. Run a trace and verify the parent delegation and glue.
  4. Query every authoritative nameserver directly for A, SOA, and NS data.
  5. Test UDP and TCP reachability.
  6. Compare DNSSEC-validating and checking-disabled diagnostic results.
  7. Inspect aliases, dependencies, SOA serials, signatures, and server logs.
  8. Fix the identified layer, then retest authoritative and recursive paths.

Conclusion

DNS SERVFAIL is a symptom, not a root cause. The fastest route to a repair is to divide resolution into layers: client and network, recursive resolver, delegation, authoritative servers, zone data, and DNSSEC validation. Controlled queries at each layer reveal whether the fault is local, cached, unreachable, inconsistent, or cryptographically invalid—allowing you to correct the real problem instead of making speculative DNS changes.

​Dig command: Purpose, Syntax, and Examples

If you are a Linux user, you have a great built-in network diagnostic tool – the Dig command. It is a simple software that you can use through the Terminal. It serves various network diagnostics.

​Purpose of the Dig command.

Dig command is a DNS utility that is available on Linux. The purpose of the Dig command is to be able to get information about your domain quickly. You can probe different DNS record types, see if the DNS propagation has ended, and check the parameters of a particular DNS record. You can also see which are the name servers that are authoritative for a domain and see if they respond correctly.

(more…)

DNS cache: Why should you care about it?

What is DNS cache?

The DNS cache is a mechanism for storing the DNS data of previously queried domain names. Different devices, such as DNS recursive servers, mobiles, computers, and tablets, have such cache memory. It has a specific purpose: to reduce the time for resolving a domain name. Thanks to it, the DNS recursive server is not necessary to perform a complete DNS lookup every time a particular domain name is requested.

(more…)